
티스토리 뷰
Paper/TTS
[Paper 리뷰] Emo-BPO: Emotion Bidirectional Preference Optimization for Diffusion-based Emotional TTS
feVeRin 2026. 10. 23.반응형
Emo-BPO: Emotion Bidirectional Preference Optimization for Diffusion-based Emotional TTS
- 기존의 emotional Text-to-Speech model은 fine-grained control의 한계가 있음
- Emo-BPO
- Reordered same-text emotional pair를 사용하여 emotion-aligned, emotion-contrastive score function을 학습
- Auxiliary reward model과 additional annotation에 대한 의존성을 제거
- 논문 (INTERSPEECH 2026) : Paper Link
1. Introduction
- Emotional Text-to-Speech (TTS)는 intellgible, affectively expressive speech를 생성하는 것을 목표로 함
- 특히 EmoDiff, EmoMix와 같은 diffusion-based model은 emotion condition을 incorporate 하므로 controllable generation이 가능함
- BUT, 대부분의 diffusion-based emotional TTS는 pre-defined label이나 heuristic condition에 의존적임 - 한편으로 Emo-DPO, EMORL-TTS와 같은 preference optimization을 활용할 수도 있음
- BUT, 해당 방식은 Classifier-Free Guidance (CFG)로 인해 non-preferred emotion mode를 반영하기 어려움
- 특히 EmoDiff, EmoMix와 같은 diffusion-based model은 emotion condition을 incorporate 하므로 controllable generation이 가능함
-> 그래서 preference-aligned, preference-contrastive trajectory를 모두 modeling 하는 Emo-BPO를 제안
- Emo-BPO
- Reordered same-text emotion pair에서 emotion-aligned, emotion-contrastive objective를 jointly learning
- CFG-compatible contrastive guidance를 활용하여 auxiliary reward, additional annotation을 제거
< Overall of Emo-BPO >
- Emotion-aligned, emotion-contrastive objective를 jointly modeling하는 emotional TTS model
- 결과적으로 기존보다 우수한 성능을 달성
2. Method
- Preliminary: Classifier-Free Guidance
- Timestep $t$의 noisy acoustic representation $x_{t}$, conditioning variable $c$에 대해, epsilon prediction network $\epsilon_{\theta}(x_{t},c,t)$로 parameterize 된 conditional diffusion model이 주어진다고 하자
- Standard variance-preserving diffusion에서 predicted noise는 conditional score function에 비례함:
(eq. 1) $\nabla_{x_{t}}\log p_{\theta}(x_{t}|c)=-\frac{1}{\sigma_{t}}\epsilon_{\theta}(x_{t},c,t)$
- 따라서 denoising은 conditional score field를 따라 sample을 iteratively transport 하여, $p(x|c)$ 하에서 higher probability region으로 moving 하는 것으로 볼 수 있음 - 이때 Classifier-Free Guidance (CFG)는 두 condition 간의 contrastive correction을 활용해 해당 score field를 modify 함
- 즉, CFG는 $\nabla_{x_{t}}\log p_{\theta}(x_{t}|c)$를 다음과 같이 replace 함:
(Eq. 2) $\nabla_{x_{t}}\log p_{\theta}(x_{t}|c)+\omega\nabla_{x_{t}}\log \frac{p_{\theta}(x_{t}|c)}{p_{\theta}(x_{t}|c')}$
- $c'$ : reference condition, $\omega\geq 0$ : guidance strength - (Eq. 2)는 CFG가 log-likelihood ratio에 대해 gradient ascent를 수행하여 target condition $c$하에서는 probability를 increase 하고 reference condition $c'$하에서는 probability를 deacrese 한다는 것을 의미함
- Epsilon parameterization에서의 contrastive formulation은:
(Eq. 3) $\epsilon_{\theta}^{\omega}(x_{t},t)=(1+\omega)\epsilon_{\theta}(x_{t},c,t)-\omega\epsilon_{\theta}(x_{t},c',t)$
- BUT, 기존 CFG에서는 reference condition $c'$가 unconditional 하므로 competing prosodic mode 간의 stronger separation을 보장하기 어려움
- 즉, CFG는 $\nabla_{x_{t}}\log p_{\theta}(x_{t}|c)$를 다음과 같이 replace 함:
- Standard variance-preserving diffusion에서 predicted noise는 conditional score function에 비례함:
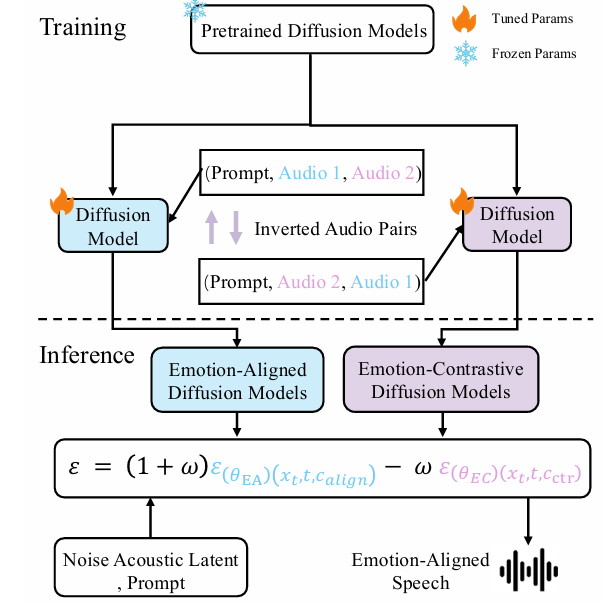
- Emotion Bidirectional Preference Optimization
- Emo-BPO는 desired emotion의 likelihood를 increase 하는 emotion-aligned objective와 alternatie emotion을 suppress 하는 emotion-contrastive objective를 jointly learning 함
- Train with Emo-BPO
- Emo-BPO는 additional annotation, auxiliary objective 없이 bidirectional emotional supervision을 수행함
- 먼저 text condition $c$에 대해, identical text을 가지지만 서로 다른 emotion label을 가지는 speech sample pair $(a_{1},a_{2})$를 구성함
- 그러면 ordered tuple $(c, a_{1},a_{2})$는 emotion-aligned direction을, 이를 reverse 한 $(c,a_{2},a_{1})$은 complementary contrastive direction을 나타냄
- $a_{1}, a_{2}$는 각각 target emotion, alternative emotion을 express 함 - 이를 통해 matched linguistic condition 하에서 emotional attraction과 emotional separation에 대한 supervision을 제공할 수 있음
- 그러면 ordered tuple $(c, a_{1},a_{2})$는 emotion-aligned direction을, 이를 reverse 한 $(c,a_{2},a_{1})$은 complementary contrastive direction을 나타냄
- 특히 논문은 해당 opposing direction을 capture 하기 위해 두 개의 dedicated diffusion branch를 optimize 함
- 먼저 emotion-aligned branch는 target emotion에 대한 conditional score field를 modeling 함
- 즉, clean audio sample $a_{1}$에 대해 standard forward diffusion process를 따라 noisy version $x_{t}$를 얻은 다음 denoising objective를 minimize 함:
(Eq. 4) $\mathcal{L}_{align}=\mathbb{E}_{t,\epsilon}\left[\left|\left| \epsilon-\epsilon_{\theta_{EA}}\left(x_{t},c_{align},t\right)\right|\right|_{2}^{2}\right]$
- $\epsilon$ : Gaussian noise, $t$ : diffusion timestep, $c_{align}$ : target-emotion condition, $\epsilon_{\theta_{EA}}$ : aligned branch의 score predictor - Emotion-contrastive branch는 competing emotional characteristic에 대한 score direction을 modeling 하기 위해, alternative-emotion sample $a_{2}$에 대한 다음 formulation을 minimize 함:
(Eq. 5) $\mathcal{L}_{ctr}=\mathbb{E}_{t,\epsilon}\left[\left|\left| \epsilon-\epsilon_{\theta_{EC}}\left(x_{t},c_{ctr},t\right)\right|\right|_{2}^{2}\right]$
- $c_{ctr}$ : alternative-emotion condition, $\epsilon_{\theta_{EC}}$ : score predictor
- 두 branch는 동일한 diffusion architecture를 가지지만 서로 다른 optimization objective를 사용함
- Aligned branch는 target emotion 하에서 likelihood를 increase 하고 contrastive branch는 competing emotional mode와의 separation을 modeling 함
- Inference with Emo-BPO
- 추론 시에는 emotion-aligned, emotion-contrastive score predictor가 contrastive guidance를 통해 combine 되어 final noise estimate를 생성함:
(Eq. 6) $\epsilon^{\omega}(x_{t},t)=(1+\omega(t))\epsilon_{\theta_{EA}}(x_{t},c_{align},t) -\omega(t)\epsilon_{\theta_{EC}}(x_{t},c_{ctr},t)$
- $t$ : diffusion timestep, $\epsilon_{\theta_{EA}},\epsilon_{\theta_{EC}}$ : aligned/contrastive branch - (Eq. 6)에서 substraction term은 competing emotional characteristic을 suppress 하고 amplified aligned term은 target emotion을 strengthen 함
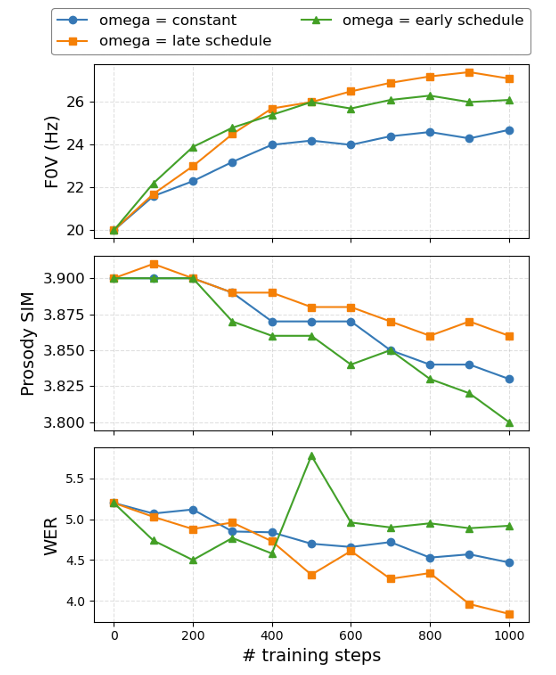
- 추가적으로 논문은 emotional expression을 progressively refine 하기 위해 late-step guidance schedule $\omega(t)=1-\frac{t}{T}$를 도입함
- 해당 schedule은 early timestep에서는 weaker guidance를 적용해 coarse acoustic structure를 preserve 하고 later timestep에서는 guidance를 gradually increase 하여 fine-grained prosodic/emotional cue를 enhance 함
- 추론 시에는 emotion-aligned, emotion-contrastive score predictor가 contrastive guidance를 통해 combine 되어 final noise estimate를 생성함:
3. Experiments
- Settings
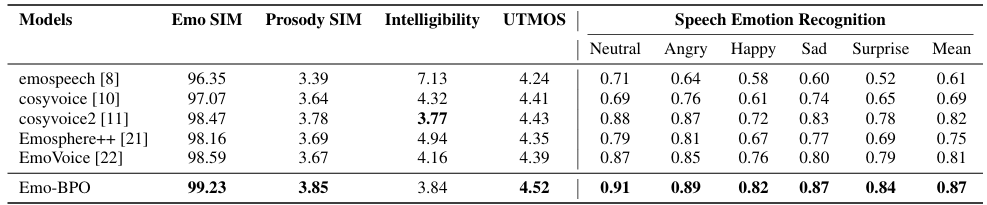
- Dataset : ESD, EmoVoiceDB
- Comparisons : CosyVoice, CosyVoice2, EmoVoice, EmoSphere++, EmoSpeech
- Results
- 전체적으로 Emo-BPO의 성능이 가장 뛰어남
- MOS 측면에서도 우수한 성능을 보임
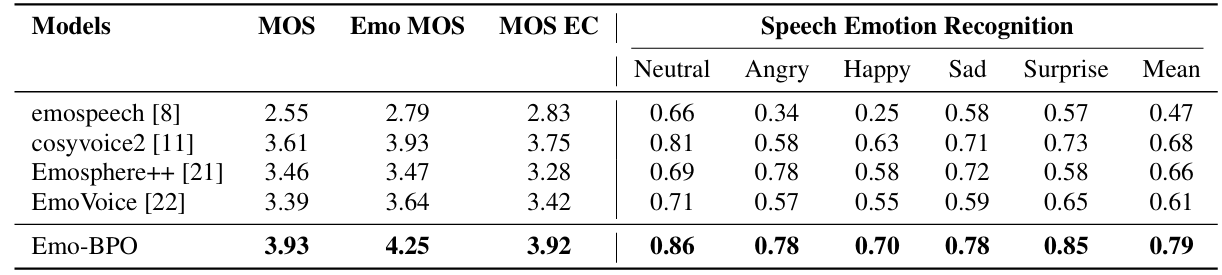
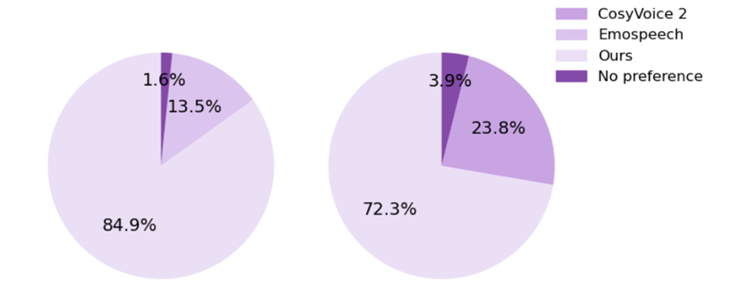
- AB test에서도 Emo-BPO가 가장 선호됨
- Ablation Study
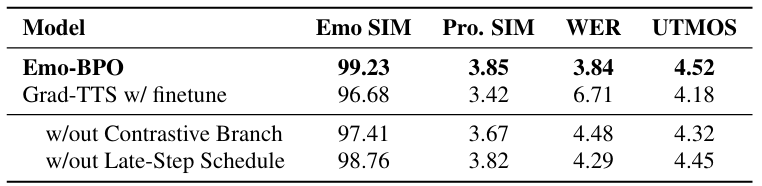
- 각 component는 성능 향상에 유효함
- Later stage에서 guidance를 scheduling 하면 더 나은 성능을 달성할 수 있음
반응형
'Paper > TTS' 카테고리의 다른 글
댓글